1
5 IMPORTANT INFORMATION ON ALIGNMENT WHEN MULTIPLYING REGIONS
12
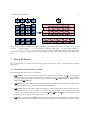
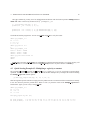
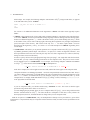
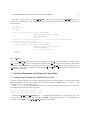
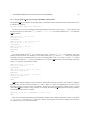
multiply_region by e252d9c145c0bf29b85b21a1ae2921fa
R1 (the source):
f4f56f08fa92494c5faa57ddcd874149 b4c06a61adbbec2f4b0ffc68e43008cb
R2 (the product): b1e34d34b031660676965b868b892043 382f12719ffe3978385f5d97540a13a1
UNIX> gf_mult e252d9c145c0bf29b85b21a1ae2921fa f4f56f08fa92494c5faa57ddcd874149 128h
b1e34d34b031660676965b868b892043
UNIX> gf_div 382f12719ffe3978385f5d97540a13a1 b4c06a61adbbec2f4b0ffc68e43008cb 128h
e252d9c145c0bf29b85b21a1ae2921fa
UNIX>
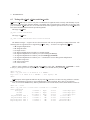
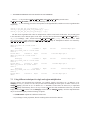
5 Important Information on Alignment when Multiplying Regions
In order to make multiplication of regions fast, we often employ 64 and 128 bit instructions. This has ramifications
for pointer alignment, because we want to avoid bus errors, and because on many machines, loading and manipulating
aligned quantities is much faster than unalinged quantities.
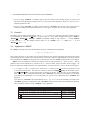
When you perform multiply region.wxx(gf , source, dest, value, size, add), there are three requirements:
1. The pointers source and dest must be aligned for w-bit words. For w = 4 and w = 8, there is no restriction;
however for w = 16, the pointers must be multiples of 2, for w = 32, they must be multiples of 4, and for
w ∈ {64, 128}, they must be multiples of 8.
2. The size must be a multiple of ⌈ w8 ⌉. With w = 4 and w = 8, ⌈ w8 ⌉ = 1 and there is no restriction. The other
sizes must be multiples of ⌈ w8 ⌉ because you have to be multiplying whole elements of GF (2w ).
3. The source and dest pointers must be aligned identically with respect to each other for the implementation
chosen. This is subtle, and we explain it in detail in the next few paragraphs. However, if you’d rather not figure
it out, the following recommendation will always work in GF-Complete:
If you want to be safe, make sure that source and dest are both multiples of 16. That is not a
strict requirement, but it will always work!
If you want to relax the above recommendation, please read further.
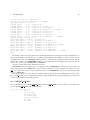
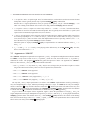
When performing multiply region.wxx(), the implementation is typically optimized for a region of bytes whose
size must be a multiple of a variable s, and which must be aligned to a multiple of another variable t. For example,
when doing multiply region.w32() in GF (216 ) with SSE enabled, the implementation is optimized for regions of
32 bytes, which must be aligned on a 16-byte quantity. Thus, s = 32 and t = 16. However, we don’t want multiply region.w32() to be too restrictive, so instead of requiring source and dest to be aligned to 16-byte regions, we
require that (source mod 16) equal (dest mod 16). Or, in general, that (source mod t) equal (dest mod t).
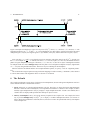
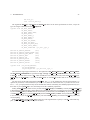
Then, multiply region.wxx() proceeds in three phases. In the first phase, multiply.wxx() is called on successive
words until (source mod t) equals zero. The second phase then performs the optimized region multiplication on
chunks of s bytes, until the remaining part of the region is less than s bytes. At that point, the third phase calls
multiply.wxx() on the last part of the region.
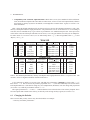
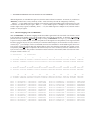
A detailed example helps to illustrate. Suppose we make the following call in GF (216 ) with SSE enabled:
multiply region.w32(gf , 0x10006, 0x20006, a, 274, 0)