1
10
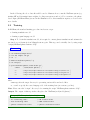
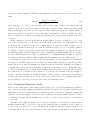
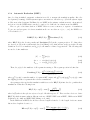
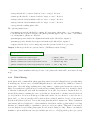
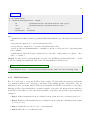
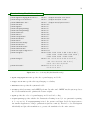
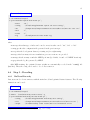
-dev specifies the development set for weight tuning.
-c specifies the configuration file generated in the previous steps.
-nref specifies how many reference translations per source-sentence are provided.
-r specifies how many rounds MERT performs (by default, 1 round = 15 MERT iterations).
-l specifies the log file generated by the MERT program.
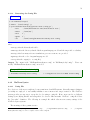
Output: The optimized feature weights are recorded in the configuration file ”NiuTrans/work/NiuTrans.phrase.user.config”. They will then be used in decoding test sentences.
2.5
Testing
If all the above steps are finished, the training of translation system is over. The learned model (including
translation table, n-gram LM and etc.) is then used to translate new sentences. Decoding new sentences
is trivial in NiuTrans. Please do it as follows:
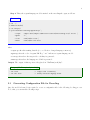
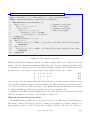
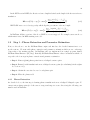
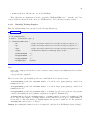
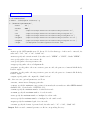
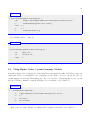
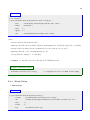
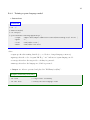
Command
$ perl NiuTrans-phrase-decoder-model.pl \
-test
../sample-data/sample-submission-version/Test-set/Niu.test.txt \
-c
../work/NiuTrans.phrase.user.config \
-output 1best.out
where
-test specifies the test data-set (one sentence per line).
-c specifies the configuration file.
-output specifies the file of translation result (the result is dumped to ”stdout” if this option is not
specified).
Output: 1-best translation of the test sentences. See file ”1best.out” in ”NiuTrans/scripts/”.
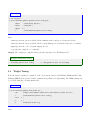
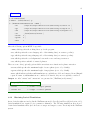
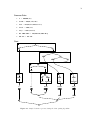
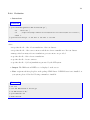
Output (NiuTrans/scripts/)
- 1best.out
2.6
B 1-best translation of the test sentences
Evaluation
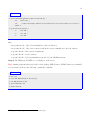
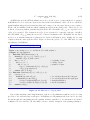
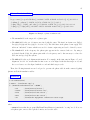
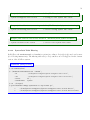
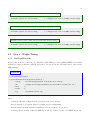
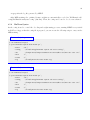
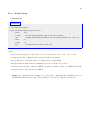
Last, the result is evaluated in terms of BLEU score. The following scripts can help you do this (mtevalv13a.pl is required for BLEU calculation1 ).
1
ftp://jaguar.ncsl.nist.gov/mt/resources/mteval-v13a.pl