1
f1 ⋅ ⋅ ⋅ ⋅ ⋅ fk ⋅ Rn in two ways: Either as successive divisors f1 ⋅ (f2 ⋅ (... ⋅ Rn )) or as an
intersection product (f1 ⋅Rn )⋅⋅ ⋅ ⋅⋅(fk ⋅Rn ). Since successive divisors of rational functions
appear in many formulas and constructions, it is interesting to see which method is
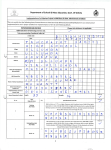
faster. Table 9.3 compares this for k = 2. We take f and g to be random tropical
polynomials with 5 terms and average over 50 runs. As we can see, the intersection
product is significantly faster in low dimensions, but its computation time grows much
more quickly: For n = 8, the intersection product takes seven times as long as the
divisors.
n
n
n
n
n
n
=
=
=
=
=
=
3
4
5
6
7
8
Successive:
f ⋅ (g ⋅ Rn )
0.62
0.68
1.04
1.42
1.5
1.6
Product:
(f ⋅ Rn ) ⋅ (g ⋅ Rn )
0.14
0.24
0.38
0.84
2.7
11.66
Ratio:
tsucc /tprod
4.43
2.83
2.74
1.69
0.56
0.14
Table 9.3.: Comparing successive divisors to intersection products. Time is given in
seconds.
Matroid fan computation
Here we compare the computation of matroid fans with different algorithms. Table
9.4 displays the results, in seconds rounded down.
We start with the computation of the moduli space Mtrop
0,n , first as the Bergman fan
B(Kn−1 ) of the complete graph on n − 1 vertices using the TropLi algorithms, then
combinatorially as described in Corollary 4.2.8. Finally, we also compute the Bergman
fan using the normal fan Algorithm 5 and in its fine subdivision (Definition 3.1.4). Note
that a-tint computes flats using a brute force algorithm. While the last method is
much faster than the normal fan algorithm, it still becomes infeasible rather quickly.
We then compare the performance of the TropLi algorithms [R1] in the case of general
matroids. First, we compute the Bergman fan of the uniform matroid Un,k . Note
that we compute it as a Bergman fan of a matroid without making use of the matrix
structure behind it (the uniform matroid is actually realizable). Then we compute two
linear matroids, i.e. we let TropLi make use of linear algebra to compute fundamental
circuits. Ci has as column vectors the vertices of the i-dimensional unit cube (in affine
coordinates, i.e. with an additional row of ones on top). Here we see again that the
method computing chains of flats is much faster than the normal fan algorithm, but
time consumption increases very quickly with matroid complexity.
113